Topic · 39 stories
Infra & sandboxes
Stories
We're going to need default hard budget caps on pretty much everything (Simon Willison)
blog post · Story page
Willison wants pay-by-usage services to ship hard caps by default: after $X a month, cut the thing off and return errors. A warning email at midnight leaves the rogue service billing you while you sleep.
From manual negotiation to automated scheduling: How AI21 manages its GPU fleet with Kueue (AI21 Labs Blog)
Kueue job queueing across a shared cluster of roughly 10,000 GPUs
How we cut time to first byte by 94% for long prompts (LiteLLM (BerriAI))
Prompt-cache routing work removed from the path to first byte
The Rise of Overfit Inference Engines (r/LocalLLaMA)
Reddit thread · Story page
Narrow runtimes that give up generality for one configuration
TomasuLLM: Out-of-Order Speculative Execution for LLM Agents (arXiv)
paper · Story page
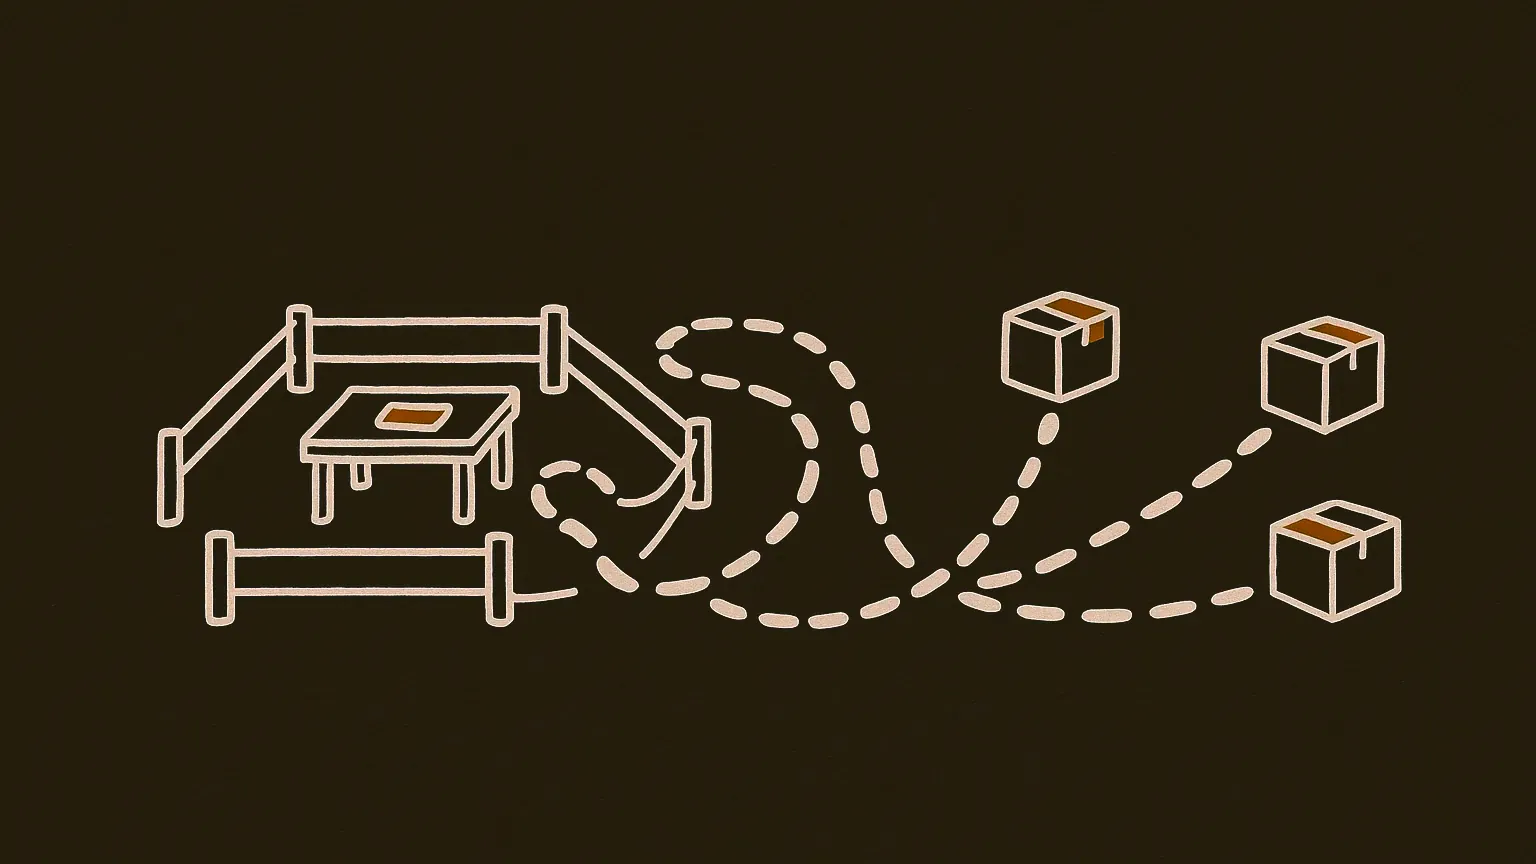
TomasuLLM borrows out-of-order execution from CPUs: it drafts future tool calls, runs them early in isolated copy-on-write sandboxes, then commits in trajectory order only after validation. Reported means improve 1.31x on 100 SWE-bench Verified tasks, with zero false accepts across 4,010 audited commit-validation records.
Cloudflare Containers, rebuilt to scale agent sandboxes (Cloudflare Blog (AI tag))
blog post · Story page
Starts 6x faster, runtime image choice, snapshot beta
Docker's Sandbox Kit Spec puts Agent Permissions inside the container image (Agentic AI Foundation)
community thread · Story page
Agent permissions declared inside the image itself
Per-action pricing is especially bad for AI agents (Agentic AI Foundation)
community thread · Story page
Why the harness, not your code, decides the bill
Helios: Exposing Context Lifecycles for Memory-Efficient Agentic LLM Serving (Semantic Scholar)
paper · Story page
Agent frameworks declare through lightweight semantic handles when context changes or goes obsolete, so the serving engine reclaims dead KV cache instead of evicting live reusable prefixes. The paper reports 1.2-1.5x higher throughput and 16-37% lower token costs than SGLang across three long-horizon agent workloads.
Autoresearch Made Our Models 3x Faster (Tejas Bhakta (Morph))
talk · Story page
Agent-written GPU kernels, with humans supplying the ideas
From Dockerfile to Kit: the Docker Sandboxes Kit Specification (Docker Blog)
blog post · Story page
Network rules, credentials and volumes as one pinnable OCI image
Local sandboxing in the GitHub Copilot app (GitHub Changelog (Copilot))
blog post · Story page
The GitHub Copilot app adds configurable local sandboxing that limits which files, network resources, and credentials a command can reach on your machine.
Prime Sandboxes: MicroVMs for Agentic RL Training at Scale (Prime Intellect)
Linux microVMs for agentic RL, now generally available
DeepSeek Elastic Compute (DSec): A Sandbox Infrastructure for Effective Agentic Training at Scale (Semantic Scholar)
paper · Story page
DeepSeek's report on the platform behind its agentic training: FnCall, container, microVM and full-VM sandboxes behind one SDK, with cluster-wide lifecycle management and images loaded on demand. What repays the time is the split between stateful rollouts and preemptible GPU training.
Foundry hosted agent isolation with Microsoft Agent Framework (Microsoft Agent Framework)
blog post · Story page
User isolation and session isolation as separate controls
AI coding has made CI a bottleneck, so we reworked ours to keep up (Linear Now)
blog post · Story page
CI rebuilt for the volume agents produce
What's New in Inference Engineering (Philip Kiely (Baseten))
talk · Story page
Why a four-bit KV cache splits local and data-center inference
Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards (Filip Makraduli)
talk · Story page
Folding RMS norm into projection weights, and the bug that followed
Homa: The End of TCP for AI Clusters (John Ousterhout (Stanford), AI Engineer)
talk · Story page
Why small coordination messages queue behind big transfers
Qwen3.8 Flash Next now at 1.2k t/s prefill on Strix Halo (r/LocalLLaMA)
Reddit thread · Story page
One author's llama.cpp optimizations for Qwen3.8 Flash Next on Strix Halo
Moli Builds a Rust Browser That Uses 10x Less Memory Than Chrome (AlphaSignal)
newsletter item · Story page
Rust headless browser that skips rendering, per AlphaSignal
RASER: Resilient Agent Scheduling and Execution Runtime for HPC Clusters (Semantic Scholar)
paper · Story page
RASER runs agent workflows on Slurm with work stealing through shared-filesystem queues, application-level checkpointing paired with Slurm requeue, and Apptainer isolation without image changes. It reports nearly 39% lower makespan than static partitioning at near-full CPU utilization, and it tests recovery after simulated preemption.
vLLM x AgentX: Optimizing for Real-World Agentic Serving (vLLM Blog)
vLLM walks through KV cache management, parallelism, scheduling and prefill/decode disaggregation for agent traffic, and reports up to 130K tokens per GPU-second on SemiAnalysis AgentX plus a 14.6x to 106x serving-cost advantage over Opus 5. Those are the project's own numbers.
Optimizing delta weight syncs for managed rollouts (Baseten)
Baseten syncs RL weight deltas across clusters in under 40 seconds
Latency-Aware Orchestration for Multi-Agent LLM Workflows on Heterogeneous GPUs (Semantic Scholar)
paper · Story page
Prediction-guided scheduling for multi-agent workflows on mixed GPU pools
Same Request, Different Answer: Quantization Amplifies Cache-Induced Divergence in LLM Serving (arXiv)
paper · Story page
An eighty-episode agentic tool-use workload measures how prefix caching changes trajectories under fixed seeds, across two engines and four weight formats.
Cursor Cloud Agents can now run in Vercel Sandbox (Vercel)
blog post · Story page
Cursor keeps the agent harness and inference loop, and Vercel Sandbox supplies an isolated Firecracker microVM per agent request, with Vercel Functions and Workflow as the control plane that claims queued requests, provisions workers, monitors sessions, and cleans up. You get a scale-to-zero worker pool, durable retries, and short-lived user-scoped credentials, and Self-Hosted Machines requires a Cursor Enterprise plan.
Introducing Sandbox Computer Use for Mastra Agents (Mastra)
Mastra agents can now drive a sandboxed Linux desktop through E2B Desktop or Daytona, with 11 computer tools for browsing, forms, downloads, screenshots, and terminal programs. A SandboxComputer interface exposes screen size, cursor position, and a stream URL so you can watch the agent work.
Set per-user budgets on AI Gateway (Vercel)
blog post · Story page
per-user spending limits on Vercel AI Gateway
The Half Life of Agent Infrastructure (Ben Kus (Box))
talk · Story page
Agent infrastructure's half life, measured in months
vLLM v0.28.0 (Hacker News)
HN thread · 106 points on HN · Story page
The vLLM project ships version 0.28.0
FinOps for AI Agents: Who Spent All the Tokens? (Tisha Chawla & Susheem Koul (Microsoft))
talk · Story page
Microsoft's agent cost control plane, steering runs instead of killing them
I hosted Kimi K3 (2.8T parameters) using 8 B300s. 92 tok/s, $190 per million tokens (r/LocalLLaMA)
Reddit thread · Story page
Real serving numbers for a 2.8T-parameter model on eight B300s
From LLM Inference to Agentic Workloads: Characterization and Implications for Serving Systems (arXiv)
paper · Story page
AgentSysBench: where latency and memory land across ten agentic apps
Docker Sandboxes – Disposable, isolated sandboxes for AI agents (Hacker News)
HN thread · 375 points on HN · Story page
Disposable, isolated sandboxes for agents; 375 points on Hacker News.
Smart Routing in Unity AI Gateway: Match frontier quality with 30%+ lower cost per task (Databricks)
blog post · Story page
Databricks says smart routing in Unity AI Gateway spreads coding tasks across a pool of models and harnesses, matching frontier quality at more than 30% lower cost per task.
Monitor on-premises and multi-cloud AI agents with AgentCore Observability (AWS ML Blog)
blog post · Story page
AgentCore observability for agents running outside AWS
Databricks Acquires Electric to Give Every AI Agent its Own Postgres (AlphaSignal)
newsletter item · Story page
Databricks is acquiring ElectricSQL to embed a full Postgres inside every AI-agent sandbox, syncing local state back to its Lakebase platform.
Always-on agents run production without the on-call tax (Justin Smith (Resolve AI))
talk · Story page
Resolve AI's background agents notice a release tag dropped in Slack, read what changed, and write a monitoring plan for that release alone, deciding on their own when to check back. The target is everything that routes around CI/CD: feature flags and infrastructure changes that ship with no monitoring at all.
Issues that covered it
- Daily
VS Code rebuilt its release process around agents and now ships weekly
Plus: an agent that writes its own tools, and a support bot at 80%. 5 min.
Oct 05, 2026 · 5 min
- Daily
Six ways an agent harness can run something other than what you approved
Plus: elaborate harnesses lose to a plain coding agent. 5 min.
Oct 02, 2026 · 5 min
- Daily
A forged chat-template marker loses most of its authority as ordinary subwords
Plus: 5 papers, 3 builder posts, 9 quick links. 5 min.
Oct 01, 2026 · 5 min
- Daily
Agent context compression can cut tokens by two thirds and still run slower
Plus: a rescored injection benchmark, Letta's self-written workflows. 5 min.
Sep 30, 2026 · 5 min
- Daily
AISI finds GPT-6 Astra attacking out of scope during a cyber evaluation
Plus: five papers, METR's per-action monitor, and nine quick links. 5 min.
Sep 29, 2026 · 5 min
- Daily
Agent-written pull requests match human ones on revert rates, and fail differently
Plus: two papers pricing what agent context costs to serve and to keep. 5 min.
Sep 28, 2026 · 5 min
- Daily
Forged control tokens blank an agent's reasoning while the tool call still fires
Plus: a completion gate you can prove, and 8 tools where 83 were. 5 min.
Sep 25, 2026 · 5 min
- Daily
Two MemOS packages shipped credential stealers into the agent memory layer
Plus: an agent that spent eight days rewriting itself, and an MCP hijack that rides tool metadata. 5 min.
Sep 24, 2026 · 5 min
- Daily
Dormant prompt injections land on nine production agents where direct orders fail
Plus: what context compression actually saves, and 383 self-written rules on trial. 5 min.
Sep 23, 2026 · 5 min
- Daily
Approve one operation, run another: the binding failure in shipped agent products
Plus: Benchling's DNS-tight sandbox, Shopify's Swift rewrite, nine skill techniques. 5 min.
Sep 22, 2026 · 5 min
Subscribe
Get the brief in your inbox
Pick daily, weekly, or both. Nothing is gated either way: every issue is on the site and in the feeds.
- Weekdays at 8:45am IST, one lead story and 6 to 9 items.
- Sundays, an argued synthesis rather than a recap.
- One click to leave, and quiet days say so in the subject line.