Topic · 44 stories
Memory & context
Stories
Trained Agentic Context Management (arXiv)
paper · Story page
Training a model to read its own long input in ranges
Memory and dreaming: how Devin learns from working with you (Devin (Cognition))
blog post · Story page
Cross-session memories, with a daily job that reindexes them
Agents don't need memory, they need documentation (liao.gg)
HN thread · 200 points on HN · Story page
Linked without a summary: the fact-gate could not verify one against the source.
Testing memory placement against compaction cliff (Mem0)
Ten repo rules through Claude Code compaction, three placements
How we built long-term memory for Alyx: why we chose a file over a knowledge graph (Arize)
blog post · Story page
One 8,000-character file instead of retrieval or a knowledge graph
Adapting Context Compression for Long-Horizon Agents with Counterfactual Continuations (arXiv)
paper · Story page
Which single compression event broke the run
Beyond Token Savings: A Systematic Study of Context Compression in LLM Agents (arXiv)
paper · Story page
A systematic study of what an agent compresses, when, and how much, measured across nearly 35,000 runs.
Introducing Memory Hooks (Mastra)
Hooks inside Mastra's observation and reflection cycle
Token Write Amplification in LLM-Mediated State Stores (Semantic Scholar)
paper · Story page
Keeping a persistent memory store costs an average of 8.00 write-path LLM tokens per raw context token, across five store configurations and seven agent workloads. A buffer that groups related writes brings the ratio to 3.02 without touching the backend.
Improved and fixed template for GPT-OSS (again). Includes preserve_thinking and fix for Unsloth-induced bug (r/LocalLLaMA)
Reddit thread · Story page
A chat-template fix for replayed reasoning turns
CliffCompaction: Cost-Efficient Compaction for Long-Horizon Coding Agents (arXiv)
paper · Story page
Compaction that only drops and truncates, never rewrites
Knowledge-as-Skill: A Structural Design for Autonomous Knowledge-Base Use by LLM Agents (arXiv)
paper · Story page
A knowledge base that describes itself to the agent
An Empirical Cost Attribution of Context-Compression Gateways in Multi-Turn Coding Agents (arXiv)
paper · Story page
A team instrumented Paritok, a production compression gateway, between coding agents and frontier models, then split the token bill three ways. Only tool-schema filtering, which strips a fixed block of roughly 21K to 57K tokens on a typical turn, comes out reproducibly positive; content compression returns about 2% of the cache-priced prefix per turn.
Designer-RSI: Evolving Procedural Memory from User Traffic for Agentic Graphic Design (arXiv)
paper · Story page
A frozen model works design software through 230-plus tools while a memory of natural-language skills grows from real user briefs, gated by replay checks that block any change regressing an observed success. Five rounds take GenEval2 execution success on Claude-Sonnet-4 from 72.7% to 99.3%.
I reverse-engineered Instinct's memory. Here's exactly how it works (Supermemory)
Black-box probing suggests Instinct keeps memory as git-tracked Markdown files found with grep rather than vectors, so read it as a reconstruction and not confirmed internals. The post rebuilds the same design on Supermemory in about 60 lines.
Agora: Git as Shared Memory for Collective AutoResearch (arXiv)
paper · Story page
Research claims as immutable Git commits, 13 workers, no planner
Shared Selective Persistent Memory for Agentic LLM Systems (Apple ML Research)
Every session starts from zero, discarding the configuration choices, domain constraints, data schemas and tool-use patterns that made the last one productive. Apple's answer keeps four categories of reusable context instead, arguing that persisting whole histories is token-inefficient and that irrelevant context degrades generation quality.
Protocol-Preserving Context Trimming for Agentic Workflows: Benefits, Failure Regimes, and Budget Guardrails (arXiv)
paper · Story page
Five trimming strategies compared on task success and protocol adherence
Stop Chunking Like It's 2022 (Yuval Belfer (AI21 Labs))
talk · Story page
Why the right chunk size is a property of the query
Generating running routes with GPT-6 Astra and ChatGPT Work (Simon Willison)
blog post · Story page
Simon Willison had GPT-6 Astra in ChatGPT Work build 5K and 10K running loops from OpenStreetMap data in 27 minutes, then could not retrieve the Python it ran, apparently because the thread had been compacted. His ask: keep the pre-compaction text and expose it to the agent through a tool call.
What Happens When the Model Eats the Stack? Rethinking the Research Agenda for Data Agents to Withstand the Bitter Lesson (Semantic Scholar)
paper · Story page
A position paper argues that as models improve they absorb the system layers built to cover their limits, and that what stays worth building is persistent semantic context about the data environment, served as a first-class abstraction.
Organizing Context in a Multi-Agent Harness (LangChain)
blog post · Story page
Deepagents now lets a subagent fork the supervisor's context or start isolated, which LangChain frames as the answer to what each subagent should see. Speed, cost and focus are stated as aims, not measurements.
KVMem: Virtualizing Million-Token Agent Workspaces on a Consumer GPU (arXiv)
paper · Story page
Paged KV state across GPU, host, and NVMe for agent history
Does Your Agent's Memory Survive a Model Upgrade? A Controlled Study of Memory Portability (arXiv)
paper · Story page
Which agent memory formats survive a model swap
ContextPipe: Database-Inspired Context Assembly for Long-Horizon Agents (arXiv)
paper · Story page
ContextPipe treats prompt assembly, what goes in, in what order, when to compact, as database query execution: a five-phase pipeline with a source catalog, a deterministic cache-aware optimizer, and an EXPLAIN ANALYZE style trace. A preliminary run on the SWE-bench Pro Qutebrowser subset cut tokens by 31% and LLM calls by 23% against append-only assembly, at the cost of a lower KV cache-hit ratio.
Useful Memories Become Faulty When Continuously Updated by LLMs (arXiv)
paper · Story page
Consolidated memory, where a model keeps rewriting past trajectories into a bank of lessons, helps at first, then degrades, and can fall below the no-memory baseline. Even consolidating from ground-truth solutions, GPT-5.4 failed 54% of ARC-AGI problems it had already solved without memory, while a control that keeps the raw trajectories stays competitive.
How our agents build on-brand pages with design.md (Vercel)
blog post · Story page
Vercel's public design.md for agents outside its repos
Agent memory as a file format (Hacker News)
HN thread · 157 points on HN · Story page
Linked without a summary: the fact-gate could not verify one against the source.
Chroma's Fission Protocol Stops AI Agent Swarms from Destroying Shared Memory (AlphaSignal)
newsletter item · Story page
Chroma's no-rollback concurrency protocol for shared agent memory
The Compaction Cliff in Long-Running AI Agent Memory (arXiv)
paper · Story page
A paper measures how many of an agent's safety rules survive repeated context compaction and proposes per-type retention policies.
Context as an Environment: Programmatic Context Management for Long-Horizon Agents (arXiv)
paper · Story page
Scroll backs each agent session with an append-only event log and a persistent sandboxed Python kernel, so tool outputs and history bind to variables instead of being serialized into every prompt. Only explicitly printed projections enter the working view, and evicted spans stay recoverable through landmarks tied to exact log addresses.
What the 100 biggest GitHub repos put in their AGENTS.md files (r/AI_Agents)
Reddit thread · Story page
One person read the AGENTS.md files of the 100 most-starred repos that have one and found 784 explicit prohibitions, with 90% written in must, always, never. The files read like institutional memory of agent mistakes, one oddly specific rule at a time.
CTIFoundry: An Agent-Native Corpus Scaffold for Cyber Threat Intelligence (arXiv (via papers.cool))
paper · Story page
a typed, provenance-linked corpus scaffold for threat-intel agents
The Era of Compound Engineering (Kieran Klaassen (Every/Cora))
talk · Story page
half the time shipping, half teaching the system
Memory for every agent your team uses (Zep)
One policy-governed memory shared across a user's agents
The Recall Trap: A Recall-Maximizing Retriever Configuration Reduces Issue Resolution in Fixed-Budget Code Context (arXiv)
arXiv, 6 pp · Story page
On SWE-bench Verified with a fixed 12-slot context pack, the higher-recall retriever setting served the gold file more often (0.878 vs 0.806) yet resolved fewer issues. Turning off one-chunk-per-file dedup took gpt-5.6-sol from 39.2% to 46.8% single-shot; a pre-registered Qwen3.6-27B replication gained 3.6pp.
Context Engineering in 2026 (Louis-François Bouchard, Omar Solano and Samridhi Vaid (Towards AI))
talk · Story page
Across 11 context presets on an open-source AI tutor, sending the full history beat every compaction technique on recall, cost and latency, because 97% of tokens came from cache and rewriting the context invalidates it. Full history recovered specific details 95% of the time against 32% after summarizing.
The Sleeping Agent: What Gist-Based Context Compression Loses and Why (Semantic Scholar)
paper · Story page
Gist compression beats truncation on facts, loses on temporal questions
Harnessing agent memory to build lifelong AI partners for materials scientists (arXiv)
paper · Story page
Persistent, portable agent memory for materials science
EvoGraph-Mem: Failure-Aware Editable Graph Memory for Long-Term Language Agents (arXiv)
paper · Story page
Editable graph memory that archives failed insights
Memory Harnesses for Long-Running Research Agents (Stefania Druga (Sakana.ai))
talk · Story page
Druga held the model fixed and varied only the recall policy. When everything fits in context, memory adds cost and nothing else; on long-horizon tasks a ranked decisions ledger beat vector RAG and gated recall, and even oracle memory didn't reach the ceiling.
MESA: Task-Adaptive Multi-Structure Evidence Selection for Long-Horizon Agent Memory (arXiv)
paper · Story page
Query-adaptive fusion of five memory structure views for long-horizon agents
Lessons from Studying Every Memory System (Shlok Khemani (Independent))
talk · Story page
Reverse engineering how ChatGPT and Claude build consumer memory
Controlled Memory Interference in Continual LLM Agents (arXiv)
paper · Story page
A diagnostic framework for when an agent's new information fails to overwrite the old. Relationship-specific interference sharply suppresses memory updates with little stability gain, and lexical and dense retrieval fail through distinct pathways.
Issues that covered it
- Daily
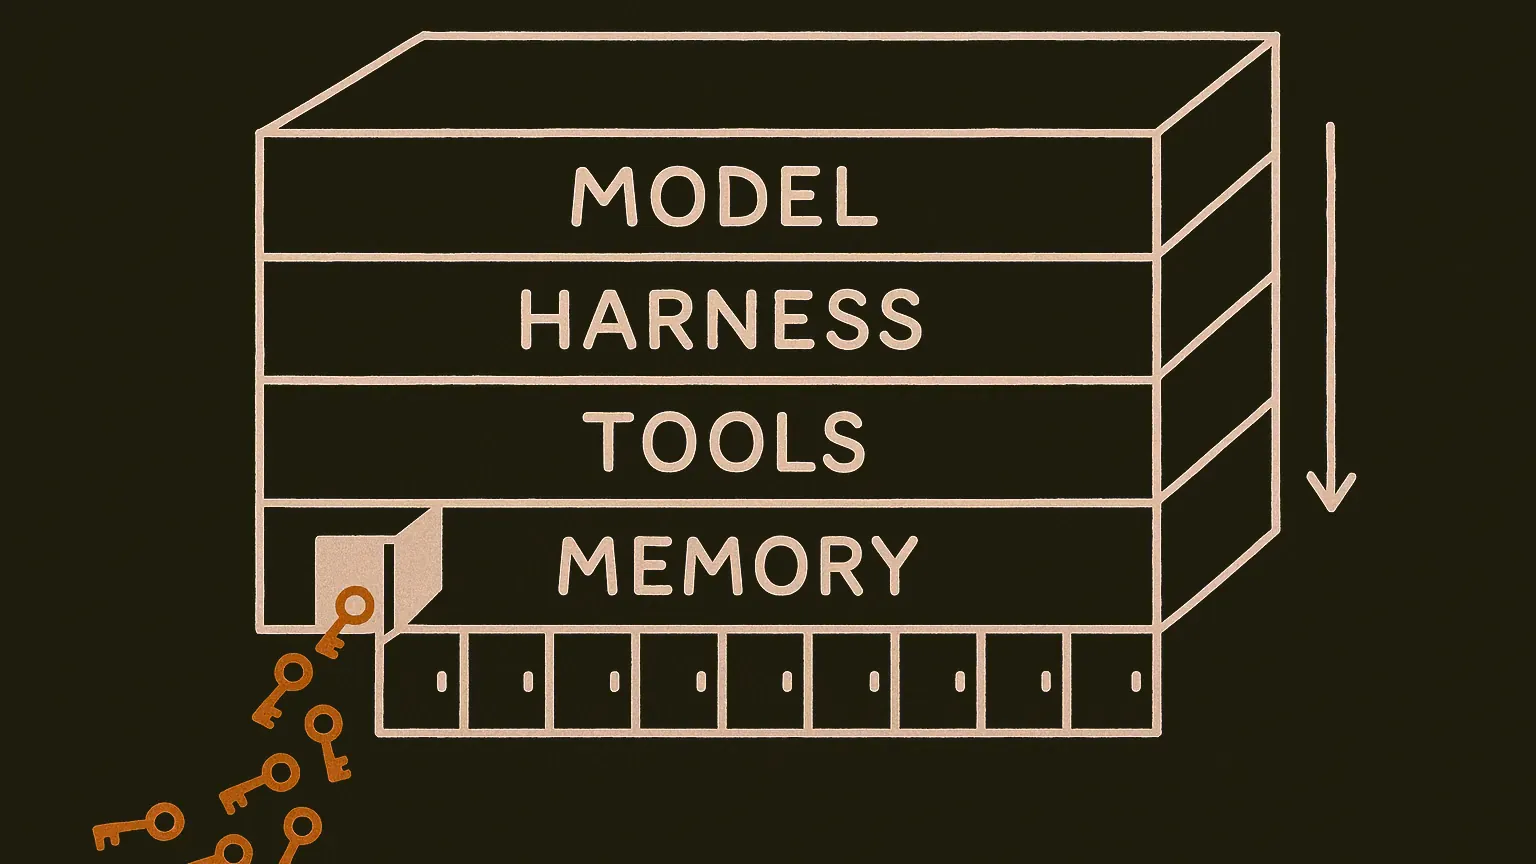
Branch steering breaks the Dual-LLM guarantee for computer-use agents
Plus: swarms borrowing public URL scanners, pipelines that go wrong under replay. 5 min.
Oct 06, 2026 · 5 min
- Daily
VS Code rebuilt its release process around agents and now ships weekly
Plus: an agent that writes its own tools, and a support bot at 80%. 5 min.
Oct 05, 2026 · 5 min
- Daily
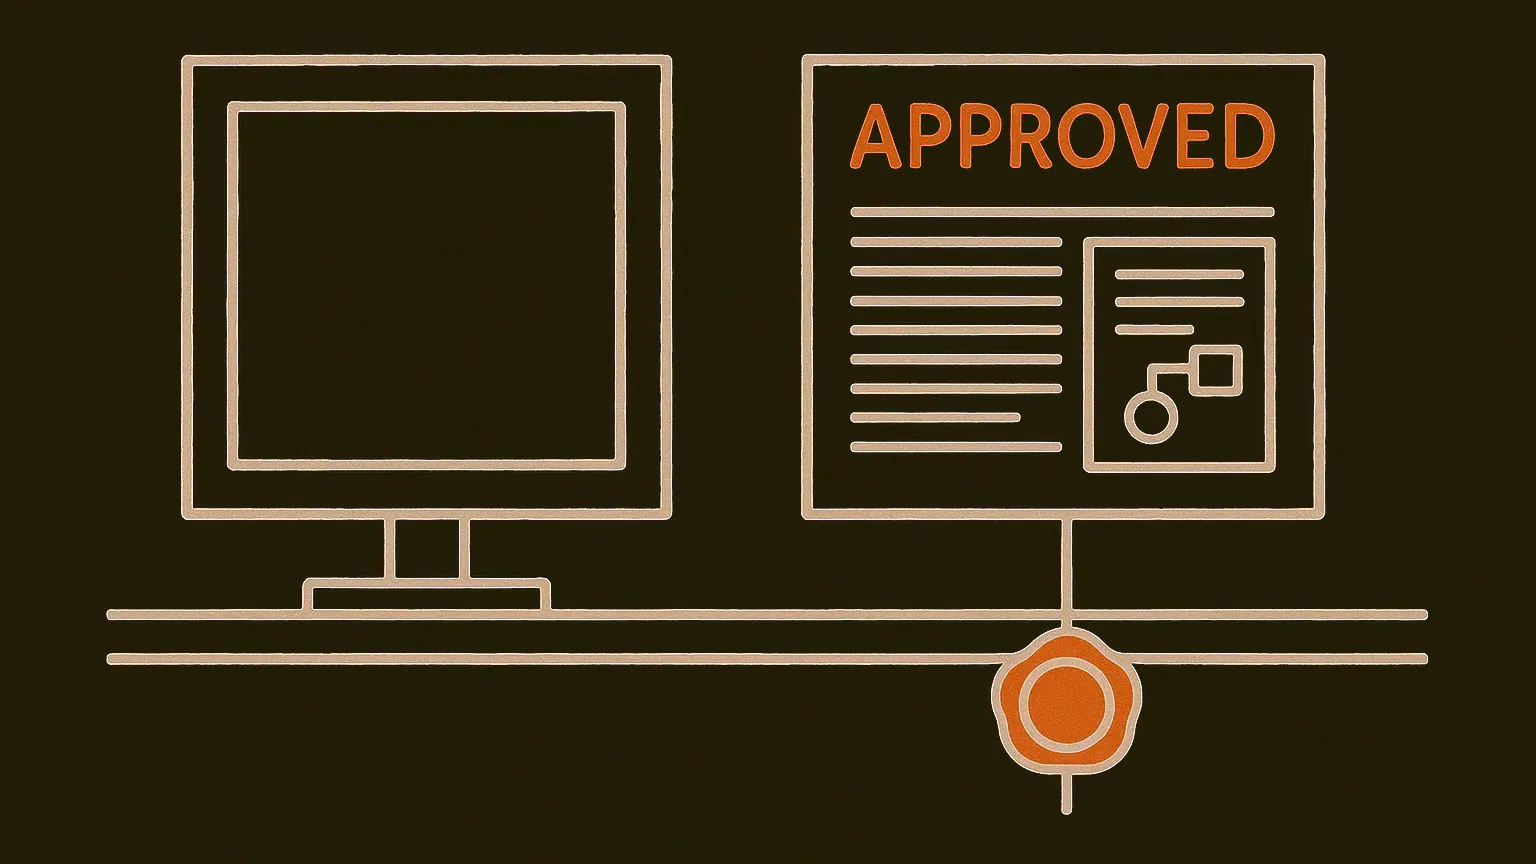
Six ways an agent harness can run something other than what you approved
Plus: elaborate harnesses lose to a plain coding agent. 5 min.
Oct 02, 2026 · 5 min
- Daily
A forged chat-template marker loses most of its authority as ordinary subwords
Plus: 5 papers, 3 builder posts, 9 quick links. 5 min.
Oct 01, 2026 · 5 min
- Daily
Agent context compression can cut tokens by two thirds and still run slower
Plus: a rescored injection benchmark, Letta's self-written workflows. 5 min.
Sep 30, 2026 · 5 min
- Daily
Agent-written pull requests match human ones on revert rates, and fail differently
Plus: two papers pricing what agent context costs to serve and to keep. 5 min.
Sep 28, 2026 · 5 min
- Daily
Two MemOS packages shipped credential stealers into the agent memory layer
Plus: an agent that spent eight days rewriting itself, and an MCP hijack that rides tool metadata. 5 min.
Sep 24, 2026 · 5 min
- Daily
Dormant prompt injections land on nine production agents where direct orders fail
Plus: what context compression actually saves, and 383 self-written rules on trial. 5 min.
Sep 23, 2026 · 5 min
- Daily
Approve one operation, run another: the binding failure in shipped agent products
Plus: Benchling's DNS-tight sandbox, Shopify's Swift rewrite, nine skill techniques. 5 min.
Sep 22, 2026 · 5 min
- Daily
Giving an agent the decoder's confidence never beat a plain deterministic gate
Plus: three agent architectures priced against the same task, and nine quick links. 5 min.
Sep 21, 2026 · 5 min
Subscribe
Get the brief in your inbox
Pick daily, weekly, or both. Nothing is gated either way: every issue is on the site and in the feeds.
- Weekdays at 8:45am IST, one lead story and 6 to 9 items.
- Sundays, an argued synthesis rather than a recap.
- One click to leave, and quiet days say so in the subject line.