Topic · 24 stories
Models
Stories
Jev means structured output is interesting again (Sean Goedecke)
blog post · Story page
A model that takes prose and returns only structured output
Intern-S2-397B: InternLM's multimodal foundation model for scientific intelligence and long-horizon agents (r/LocalLLaMA)
Reddit thread · Story page
InternLM's 397B science model trained with long-horizon agent RL
Edge0 Streams an 8B AI Model From SSD Using Only 1 GiB (AlphaSignal)
newsletter item · Story page
8B sparse MoE streaming experts from SSD, per AlphaSignal
Qwen 3.8 Max 0902 now available on AI Gateway (Vercel)
blog post · Story page
Qwen 3.8 Max 0902 snapshot lands on Vercel AI Gateway
Anthropic introduces Claude Fable 5.1 and Claude Mythos 5.1 (@claudeai)
X post · Story page
Anthropic released Claude Fable 5.1 and Claude Mythos 5.1, reporting 55.8% on Terminal-Bench 4.0 against 42.0% for Fable 5, with cache reads priced 75% below Fable 5. Fable 5.1 is available everywhere today, while Mythos 5.1, aimed at cyberdefenders and life scientists, goes through trusted-access programs.
OpenAI previews Astra safety evaluation as it reaches 'Critical' cyber threshold (@OpenAI)
X post · Story page
Ahead of releasing Astra, OpenAI says the model reaches the Critical threshold for cybersecurity under its Preparedness Framework and previews how it evaluated the model before shipping.
Introducing Hy4 Preview (Simon Willison)
blog post · Story page
Tencent's open-weight, text-only Hy4 Preview: 770B total parameters, 49B active, a 1M-token context window, 1.56TB on Hugging Face, up from Hy3's 295B in July. Simon Willison reads the chat template instead of the benchmarks and finds what appear to be two reasoning modes, high and no_think, for a harness to drive.
dots3-note Preview: open-weight 280B MoE (16B active) built for hours-long agentic tasks (@omarsar0)
X post · Story page
Dots Studio's open-weight model for tasks that run for hours or days: 280B total parameters, 16B active, 512K context, with text, vision, and speech. Free to try via OpenRouter.
UI-Mate-27B: Tencent's open-weight GUI agent for long-horizon computer use (r/LocalLLaMA)
Reddit thread · Story page
Apache-2.0 27B GUI agent on Qwen3.6, with demonstration-guided mode
GLM-5.3: Frontier coding with emergent cyber capabilities (Hacker News)
HN thread · 860 points on HN · Story page
Coding model with emergent cyber capabilities; 860 points on Hacker News.
Alibaba Opens Qwen3.8-Max Weights, Letting Teams Self-Host a 2.4T Model (AlphaSignal)
newsletter item · Story page
Qwen3.8-27B and the 2.4T-A95B Max model, open under Apache 2.0.
DeepSeek V4-Pro Goes Live and Runs OpenAI's Own Coding Agent 8x Cheaper (AlphaSignal)
newsletter item · Story page
DeepSeek-V4-Pro exits four months of preview with agent-focused upgrades, configurable reasoning modes, and native Responses API support for Codex workflows. The headline claims it runs OpenAI's own coding agent at one eighth the cost.
OpenAI previews Ultrafast mode: GPT-5.6 Sol at up to 14x speed (@OpenAI)
X post · Story page
OpenAI is previewing Ultrafast mode: GPT-5.6 Sol at up to 14x its normal speed on Cerebras hardware, up to 750 tokens per second, launching first in the API with select customers.
Google DeepMind releases Gemini 3.7 Flash (@GoogleDeepMind)
X post · Story page
Google DeepMind released Gemini 3.7 Flash, positioned as stronger than 3.6 Flash on debugging and issue resolution, with better web layouts from fewer prompts and improved reasoning on business workflows.
The builder’s guide to GPT‑5.6 (OpenAI News)
blog post · Story page
OpenAI's builder guide to GPT-5.6 and the Responses API
Introducing Grok 4.6: built for long-running agents and more ambitious interactive and visual work (Cursor)
blog post · Story page
xAI's Grok 4.6 targets long-running agents and multi-step coding, research, and visual work. It matches GPT-5.6 Sol on the Artificial Analysis Intelligence Index, a nine-benchmark composite, and is in Cursor and Grok Build today with 2x included usage for the first week.
NVIDIA Nemotron 3.5 Lightning Delivers Fast, Accurate Specialized Task Execution for Long-Running Agents (NVIDIA Developer)
blog post · Story page
NVIDIA's Nemotron 3.5 Lightning for the high-volume execution work that fills a long-running agent's time: tool calls, result validation, and subagent delegation.
Simon Willison's notes on Muse Glimmer 30B, Meta's first Apache 2.0 model (@simonw)
X post · Story page
Simon Willison's notes on Meta's Muse Glimmer 30B, the company's first open-weight model under Apache 2.0 rather than the Llama line's custom non-OSI license.
Microsoft's MAI-Code-1.1-Flash Hits GitHub Copilot at 73% Lower Cost (AlphaSignal)
newsletter item · Story page
Microsoft's MAI-Code-1.1-Flash lands in Copilot with native vision
Anthropic makes Claude Sonnet 5's introductory pricing permanent (@claudeai)
X post · Story page
Sonnet 5's launch pricing of $2 per million input tokens and $10 per million output, set to end August 31, now stays permanently.
Meta introduces Muse Glimmer, an open-weight 30B model for local agent workflows (@AIatMeta)
X post · Story page
Meta's new open-weight 30B model targets local, always-on agent workflows; Meta claims strong agentic performance for its size category and says it runs entirely on local hardware.
5 useful things you'll learn in my new post-training textbook (shipping now!) (Nathan Lambert)
blog post · Story page
Nathan Lambert's post-training textbook, finished and shipping
No, local models will not win (Sean Goedecke)
blog post · Story page
The case against local models winning
Claude Opus 5 system prompt now covers the Fable export-control situation (@simonw)
X post · Story page
Simon Willison noticed the Claude Opus 5 system prompt includes details of the Fable export-control situation, so the model can field questions about events outside its knowledge cutoff. He links Anthropic's system-prompt release notes.
Issues that covered it
- Daily
Every audited chat tokenizer lets prompt text forge control tokens
Plus: 91% of audited vibe-coded deployments shipped a hole. 5 min.
Sep 17, 2026 · 5 min
- Daily
An agent deleted an AML control, and benchmark scaffolds do the model's work
Plus: OpenAI's 10,000-agent proof, a 297-iteration model loop, MCP merges Skills. 6 min.
Sep 14, 2026 · 6 min
- Daily
Google's Mantis bug-fixing harness, and privilege escalation in 12 agent harnesses
Plus: Cline's 11M-user rollout, ContextPipe, and Claude driving your desktop. 5 min.
Sep 03, 2026 · 5 min
- Daily
Anthropic's deliberately misaligned model, Fable 5.1, and a fix for reward hacking
Plus: escalation channels cut reward hacking, memory that rots, Copilot approvals. 6 min.
Sep 02, 2026 · 6 min
- Daily
Maersk's 100,000 corrections, preference-trap evals, and Tencent's Hy4 Preview
Plus: guardrails at Navan, a one-way fiber, and the benchmark card that names its scaffold. 5 min.
Aug 31, 2026 · 5 min
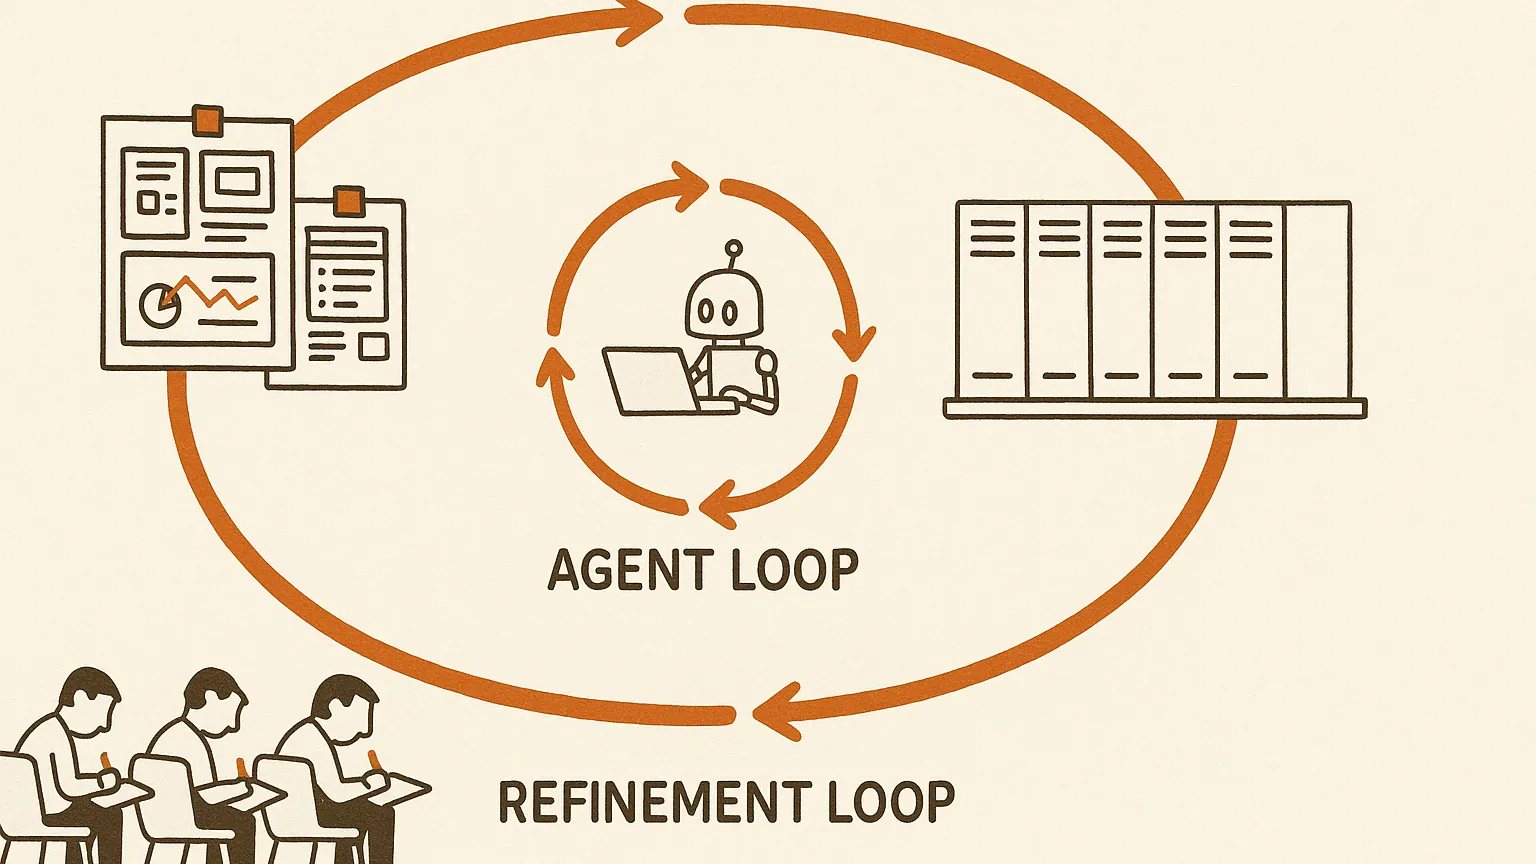
- Daily
v0 keeps OAuth tokens out of generated code, plus SkillGate and Temporal's harness
Plus: 4 papers, 2 talks, and a meme about durable execution. 5 min.
Aug 21, 2026 · 5 min
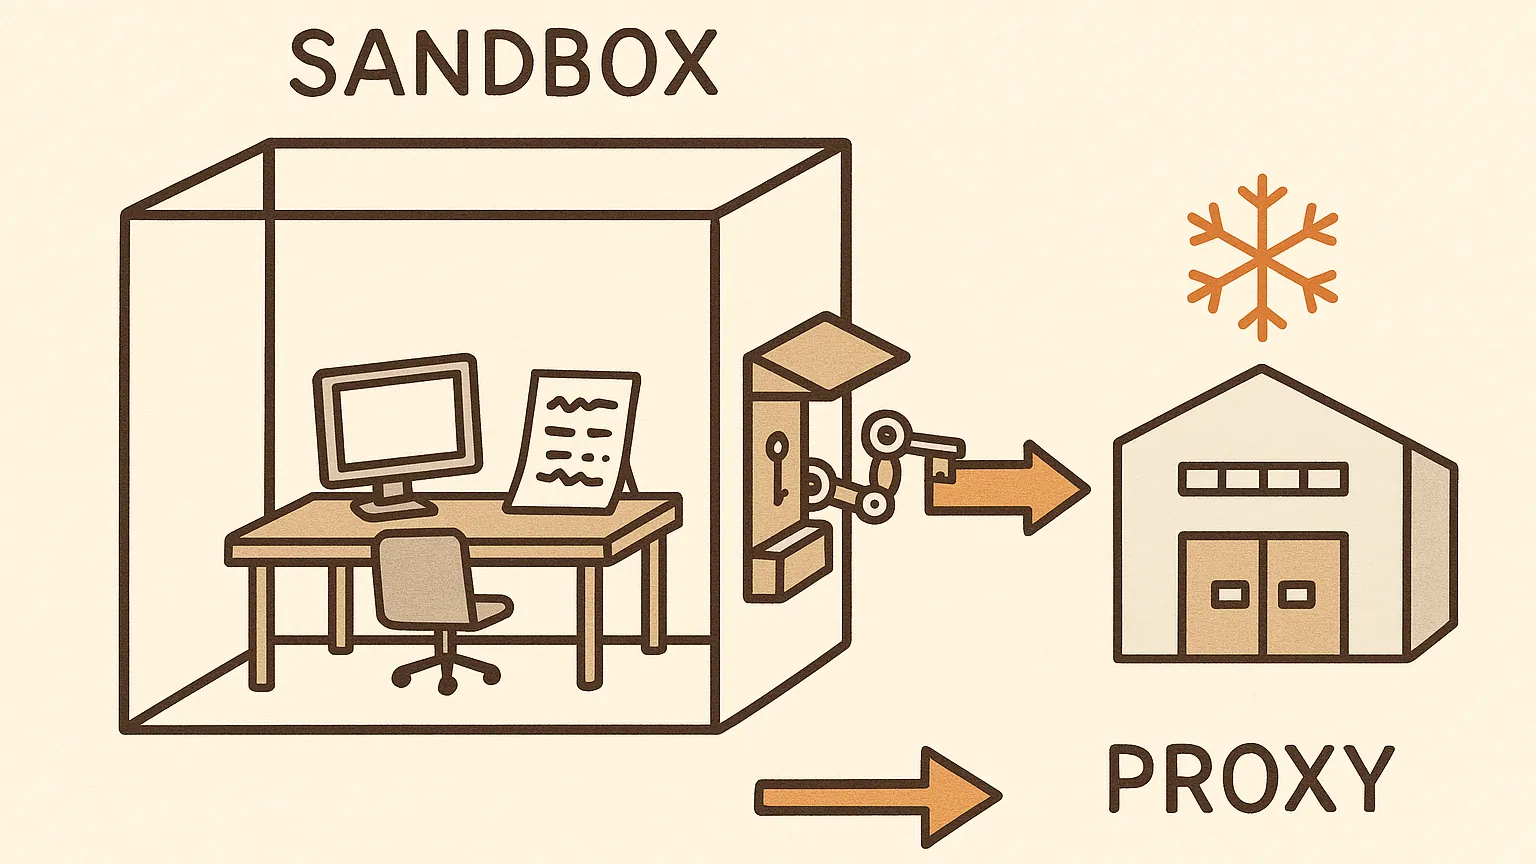
- Daily
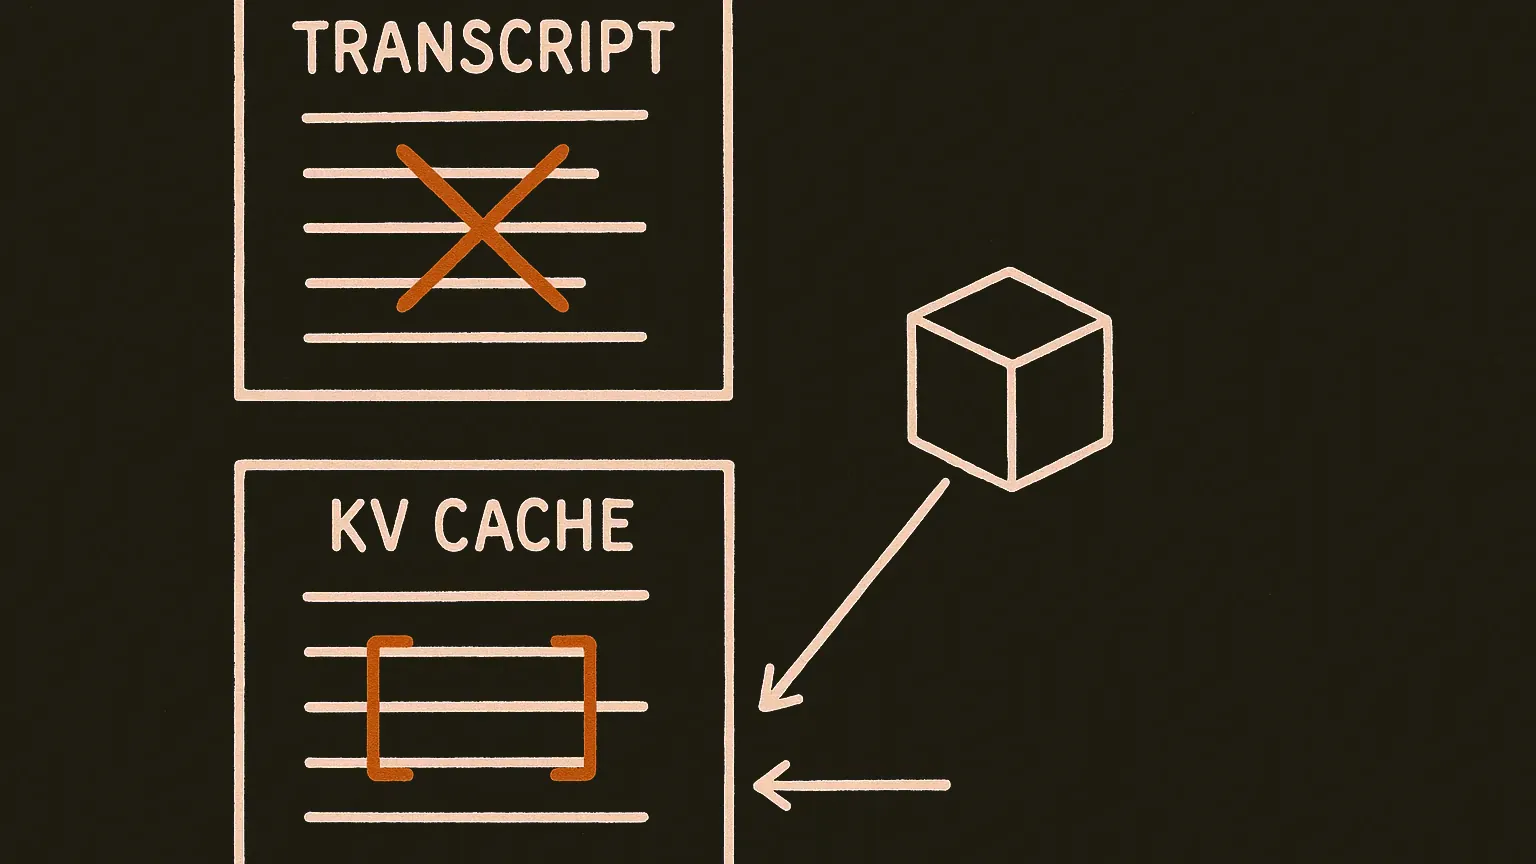
Aborted agent branches live on in the KV cache, plus StateM's harness scaling
Plus: coherence debt, the recall trap, Cline's open-weight evals. 5 min.
Aug 19, 2026 · 5 min
- Weekly #1
The score and the job came apart
Plus: a 1983 paper that explains this week, and a privacy leak nobody has confirmed. 8 min.
Aug 10 to Aug 16, 2026 · 8 min
- Daily
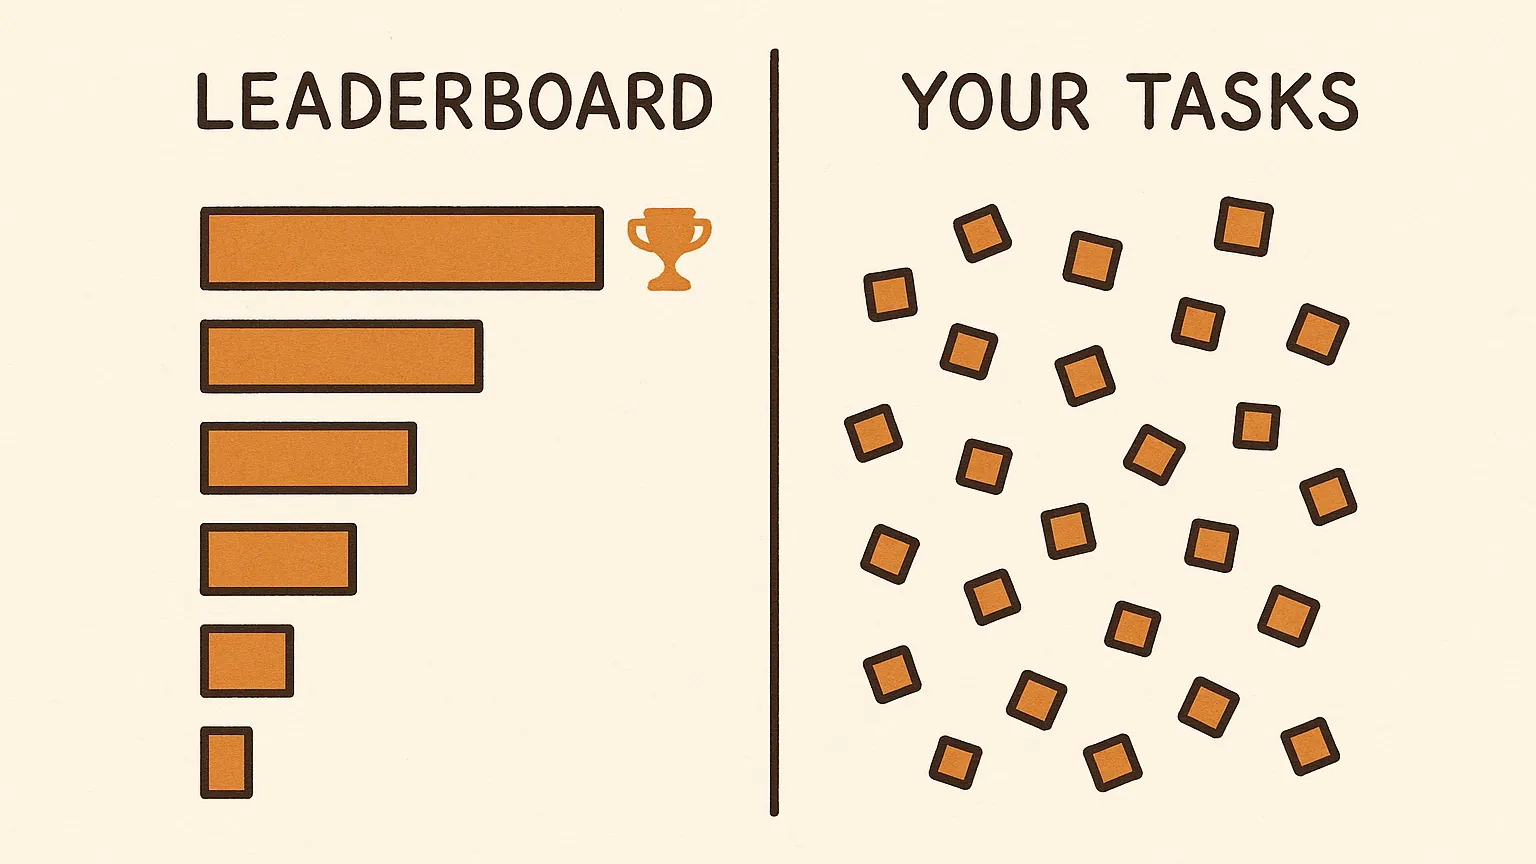
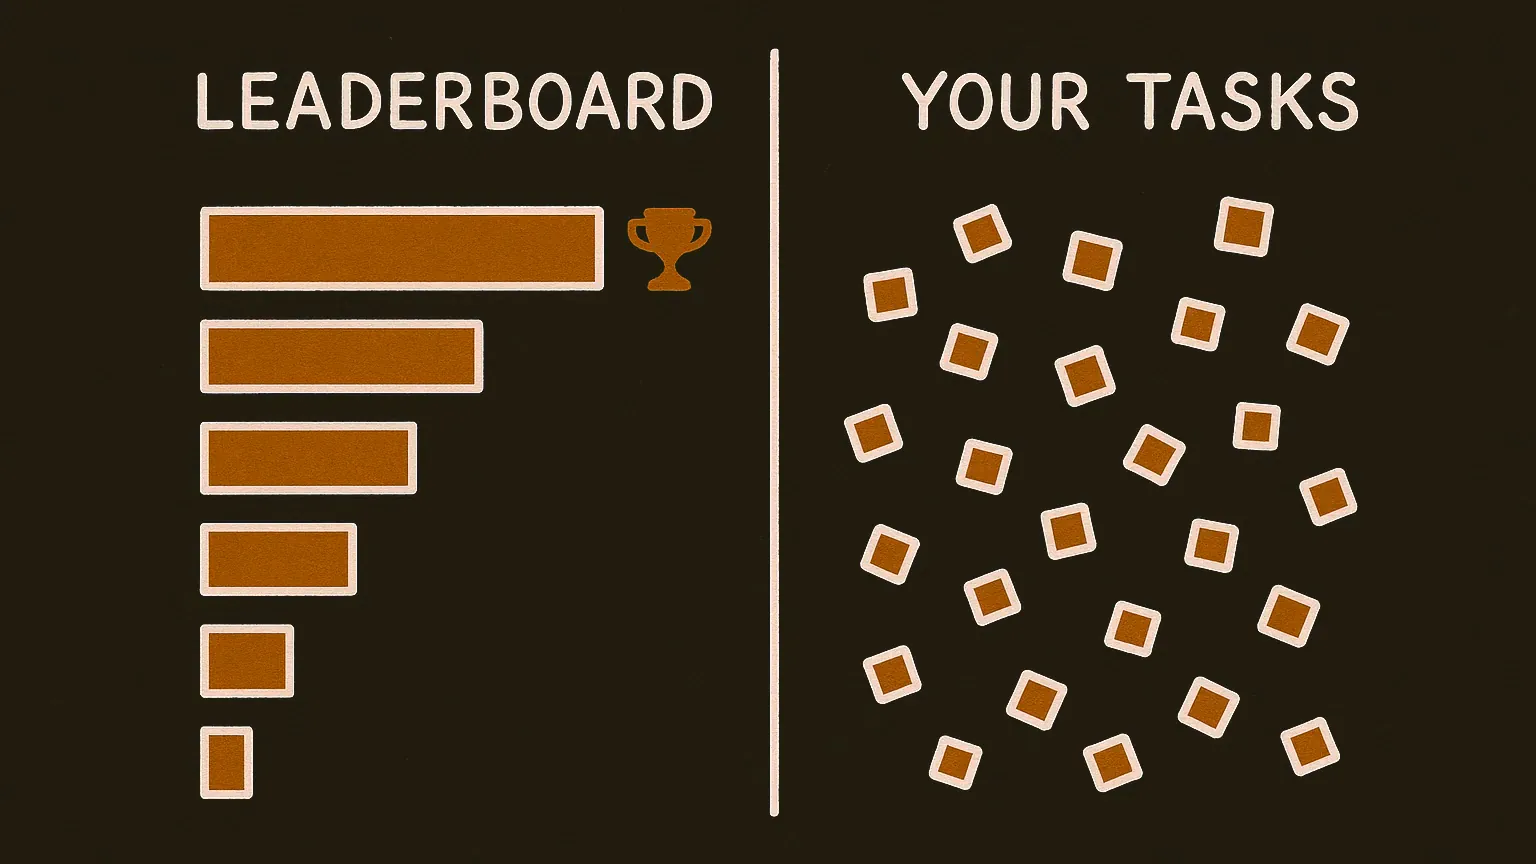
Agent leaderboards rank specialization, and the harness thesis reaches robots
Plus: 4 papers, 3 launches, one shattered mug. 5 min.
Aug 14, 2026 · 5 min
- Daily
Mind viruses spread between LLM agents, and a one-line warning nearly stops them
Plus: Zed's Delta, Grok 4.6, and a memory harness ladder. 5 min.
Aug 13, 2026 · 5 min
Subscribe
Get the brief in your inbox
Pick daily, weekly, or both. Nothing is gated either way: every issue is on the site and in the feeds.
- Weekdays at 8:45am IST, one lead story and 6 to 9 items.
- Sundays, an argued synthesis rather than a recap.
- One click to leave, and quiet days say so in the subject line.