Story · arXiv
The Double Measurement Confound in Agent Benchmarks: De-Scaffolding, Ground-Truth Scoring, and Reliability Beyond the Mean (arXiv)
paper · Story page
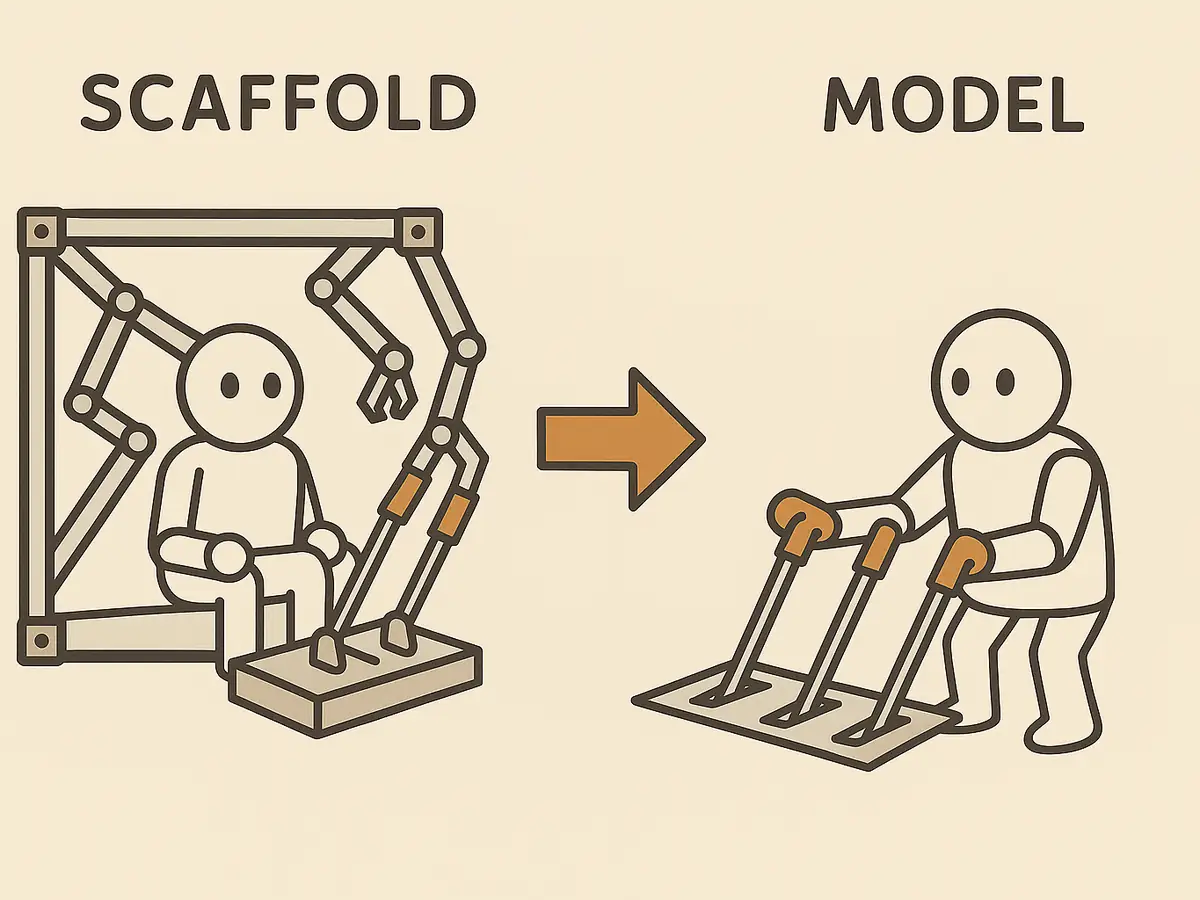
Two ways an agent benchmark can measure its own pipeline instead of the model: a fixed scaffold makes the execution-critical decisions, and the scorer may reward output shape rather than correctness. Handing those decisions to the model, scoring against seeded ground truth and reporting worst-case metrics turned ComtradeBench's nearly flat leaderboard into a spread of reliability.
In plain words
- Researchers report that changing an artificial intelligence test revealed differences in reliability that its original scores had hidden.
- They made each system choose how to carry out tasks instead of letting surrounding software make key decisions.
- They checked answers against known correct results instead of rewarding answers for having the expected format.
- For people choosing artificial intelligence systems, the revised scores distinguish options that had previously looked similarly reliable.
Appeared in
- An agent deleted an AML control, and benchmark scaffolds do the model's work
Sep 14, 2026 · in the sections
Subscribe
Get the brief in your inbox
Pick daily, weekly, or both. Nothing is gated either way: every issue is on the site and in the feeds.
- Weekdays at 8:45am IST, one lead story and 6 to 9 items.
- Sundays, an argued synthesis rather than a recap.
- One click to leave, and quiet days say so in the subject line.