Story · Lakshya A. Agrawal (GEPA)
Beating RL With Reflection: GEPA and Optimize Anything (Lakshya A. Agrawal (GEPA))
talk · Story page
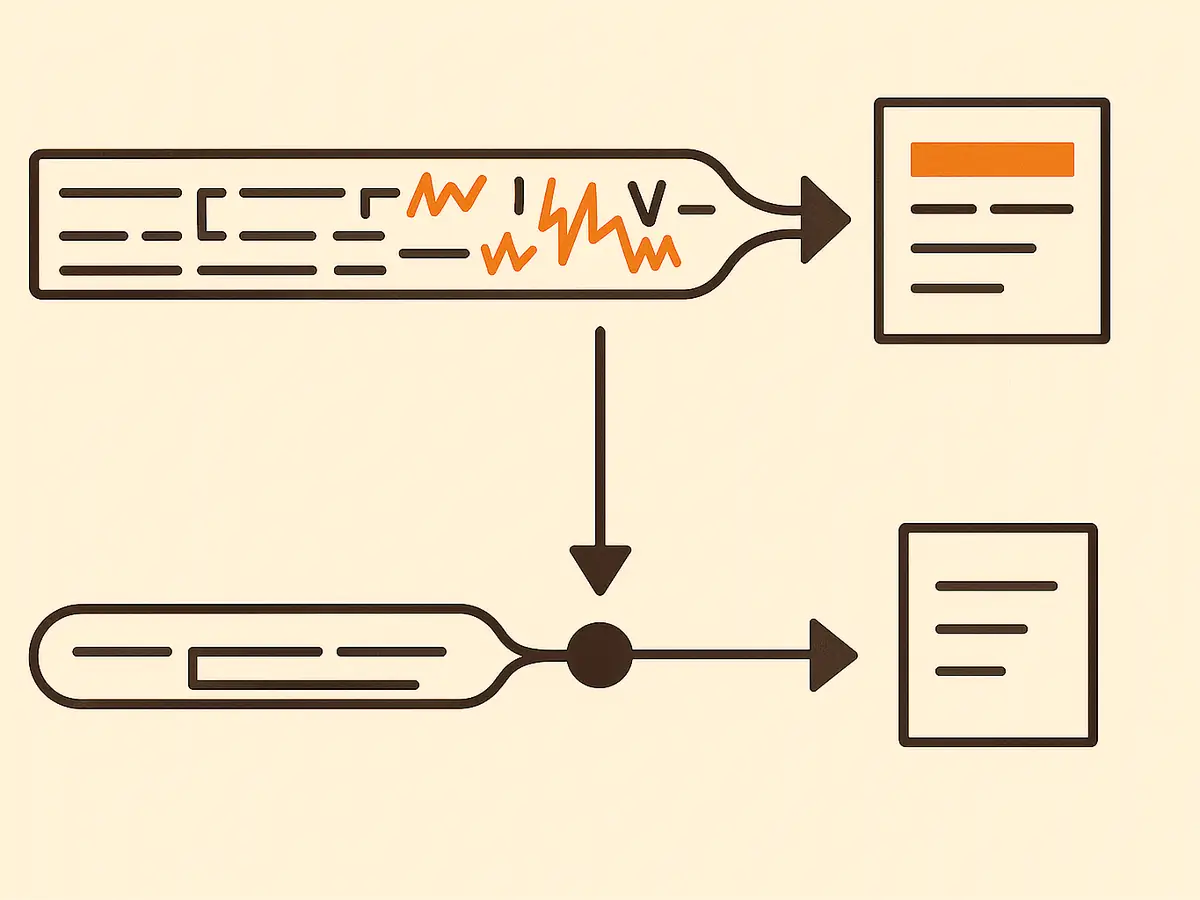
Instead of collapsing a rollout into one score, GEPA has a model read the whole trace, chains of thought, tool calls and error messages, then write a better prompt. Agrawal reports one round of reflection on three examples doubling the gains GRPO reached after 25,000 rollouts.
In plain words
- Lakshya Agrawal presented a way for artificial intelligence to improve its instructions by studying previous attempts.
- The software reads records of the steps taken and errors encountered, then rewrites the instructions for future attempts.
- It keeps several promising versions with different strengths, so later attempts can explore different ways to improve.
- Agrawal reported twice the improvement after reviewing three examples compared with a method that learned from 25,000 attempts.
- For developers, his examples show how this approach can improve both written instructions and programs that carry out tasks.
Appeared in
- Agent-written pull requests match human ones on revert rates, and fail differently
Sep 28, 2026 · in the sections
Subscribe
Get the brief in your inbox
Pick daily, weekly, or both. Nothing is gated either way: every issue is on the site and in the feeds.
- Weekdays at 8:45am IST, one lead story and 6 to 9 items.
- Sundays, an argued synthesis rather than a recap.
- One click to leave, and quiet days say so in the subject line.